Silicon Valley Technology Commentary & Archives · Est. 2006 3,031 Posts · 2006–2026

November 8, 2009

November 8, 2009 · 5 MIN READ · BY LOUIS GRAY

The Story of Google's Closure: Advanced JavaScript Tools

The Story of Google's Closure: Advanced JavaScript Tools

On Thursday, Google caught the eyes of Web developers around the world with the company's move to open source its Closure JavaScript compiler, library and template system to the Web community - the very same tools that power popular applications, including GMail, Google Docs, Google Maps, Google Reader, and no doubt many others. The Closure tools optimize Web code to be compact and high-performance, essentially reducing page load and redraw times while also enabling uncompromising capabilities. Around the Web, you could see the release elated geeks both inside and outside Google, many of whom previously worked with the tools while working for the Mountain View tech giant.

To better understand these tools, and get a real-world perspective on Closure, I reached out to Mihai Parparita, an engineer on the Google Reader team, to hear of his experience. He was gracious enough to extend a very thorough overview, explaining the tools' origin and use case, by e-mail, much of which is summarized below.

The Closure compiler dates back to GMail's launch in April of 2004. Paul Buchheit, now of Facebook, via FriendFeed and previously Google, largely credited for the founding of GMail, highlighted the announcement this week on his FriendFeed, calling it the "Gmail JavaScript compiler". The library and template system were initiated a few years following.

As Google Reader development started in early 2005, with Mihai, Jason Shellen, Chris Wetherell (the latter pair now are at Thing Labs working on Brizzly, which also uses Closure) and others working to make a top-notch Web-based RSS reader, the team leveraged Closure immediately after the initial prototypes. At the time, the team was less focused on download size than they are today, but the compiler's aggressive function checking improved error detection.

Mihai writes:
"Until the last month or so leading up to the Reader launch in October 2005, the size benefits of the compiler were less important, since we were less focused on download time (and performance in general) and more on getting basic functionality up and running. Instead, the extra checks that the compiler does (e.g. if a function is called with the wrong number of parameters, typos in variable names) made it easier to catch errors much earlier. We have set up our development mode for Reader so that when the browser is refreshed, the JavaScript is recompiled on the server and is used with the page when it is reloaded. This results in a tight development loop that makes it possible to catch JavaScript errors as early as possible."
As the library and template systems did not arrive until approximately 2006, Reader utilized homegrown code in their place that provided similar functionality, including handing different browser versions and quirks, Mihai said. But as soon as they were available, Reader used the new tools for new code, and later, to replace old shared libraries and homegrown code. Mihai said he performed an audit to detect usage of the old code, and find their Closure equivalents, so work could be distributed among the team during so-called "fixit" periods, when attention was given to code quality instead of new functionality.

With Closure implemented, benefits to Google Reader users are clear. Mihai estimates that without Closure, Reader's JavaScript code would be a massive 2 megabytes, which reduces to 513 kilobytes with Closure, and all the way down to 184 kilobytes using gzip, supported by nearly all browsers. Additional benefits include the near-elimination of concerns around browser differentiation, and an extremely manageable large JavaScript codebase "that doesn''t get out of control as it ages and accumulates features", he said. (Note download time was given as the main reason Robert Scoble has moved away from Reader and that the team recently made a push to even further optimize the code)

Closure's role at Reader, initially utilized in low level code, has "moved up the UI stack" to to the point where it is leveraged for UI widgets. Mihai says "this means that it's not a lot of work to do auto-complete widgets, menus, buttons, dialogs, drag-and-drop, etc. in Reader."

The excitement around Closure's release was palpable from developers through Silicon Valley and beyond as you could see from blog posts by Erik Arvidsson, a co-creator along with Dan Pupius, and a series of posts at bolinfest.com. Other excited Tweets came from Mike Knapp, the aforementioned Chris Wetherell and Kushal Dave.

As Mihai says, "You can tell that there's something special about this when you look at the ex-Googlers cheering about its release. If it had been some proprietary antiquated system that they had all been forced to use, they wouldn't have been so excited that it was out in the open now."

Like many other projects at Google, Closure's compiler, library and templates were derived solely as 20% projects and are largely still dependent on work done in so-called 20% time at Google. Mihai says that if one project needs a feature from the compiler or the library, they are encouraged to contribute to it as well.
"To give a specific example, Reader had some home-grown code for locating elements by class name and tag name (a much more rigid and simplified version of the flexible CSS selector-based queries that you can do with jQuery or with the Dojo-based goog.dom.query)," Mihai said. "As part of the process of "porting" to the Closure library, we realized that though there was an equivalent library function, goog.dom.getElementsByTagNameAndClass, it didn't use some of the more recent browser APIs that could it make it much faster (e.g.getElementsByClassName and the W3C Selector API). Therefore we not only switched Reader's code to use the Closure version, but we also incorporated those new API calls in it. This ended up making all other apps faster; it was very nice to get a message from Dan Pupius saying that the change had shaved off a noticeable amount of time in a common Gmail operation."
Now clearly I'm no developer beyond simple HTML and JavaScript, but I know good Web apps when I see them, and Google's Web apps (as well as Brizzly) are among the best in the world. They have managed to take what used to require massive software installs and make them relatively lightweight Web instances with similar functionality between services. With the release of Closure, sharp Web developers will be looking to leverage these JavaScript libraries and tools to make their own products best of breed - something that will benefit the Web as a whole. I appreciate Mihai's openness, and his willingness to share the story behind the story.
November 7, 2009

November 7, 2009 · 2 MIN READ · BY LOUIS GRAY

Cadmus Filters Real Time Streams to Reduce Clutter

Cadmus Filters Real Time Streams to Reduce Clutter


The more people and blogs you follow on social networks and through RSS, the more likely it is that you are going to see duplicate data, be it via retweets, forwards, or through many of your friends sending the latest viral videos or images. A new product under development, called Cadmus, looks to filter your real time streams to group similar posts in your feeds to reduce the noise. The service currently works on your Twitter account, your FriendFeed account, or on any number of blogs you add. You can also add many RSS feeds at once via OPML.


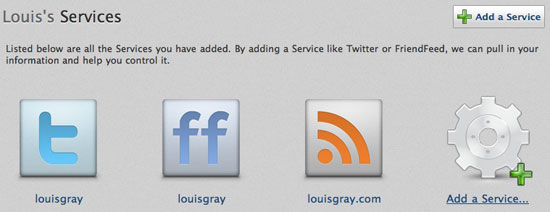
Adding Supported Services to Cadmus

In my testing of Cadmus, I found it correctly detected retweets, replies from others to the original sender, copies of tweets sent to FriendFeed, and other topically-related items, even if they did not share keywords. Cadmus was even able to find similar updates that were hours or days apart.


The Results: A Quieter Feed By About 10 Percent

On average, each refresh of Cadmus filtered around 10 percent of my updates. For runs that included 3,000 or so updates, 300 individual items would be grouped or filtered - and testing of a smaller account in the low hundreds also showed a similar 10 percent filter rate. In fact, the more updates I filtered, the higher the percentage filtering would be found. In a run comprising more than 8,000 items, almost 1,000 were "related".


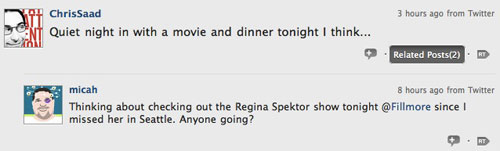
Cadmus Knew Both Micah and Chris Were Watching a Show


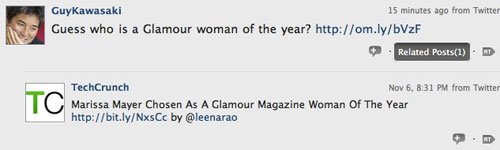
Cadmus Saw Guy Talking About an Article TechCrunch Mentioned


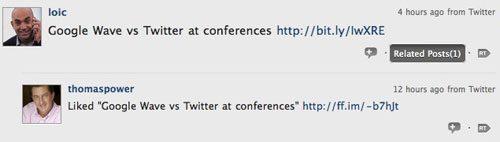
Cadmus Linked Thomas Power's Like of Loic's Share

The authors, Anomaly Innovations, who are chronicling Cadmus' development on their blog, show even higher filtering rates, of almost 30 percent, if you looked at an entire week's worth of updates. And while most of the filtered items only had one or two related posts, you can see an extreme version from the last week here.

To use Cadmus, you need to log in at http://thecadmus.com/, using OAuth, to your Twitter account, and you can add as many supported services as you like to the system. Once you have scanned your stream, click the reload button in the top right to get a newly filtered stream. If you're tired of seeing duplicates, want a stream with less noise, or just want to lump similar items, it is an interesting development - one I expect to get better as they continue to update.
November 7, 2009 · 2 MIN READ · BY LOUIS GRAY

TweetMeme to Soon Offer Individual Channels for Top Links

TweetMeme to Soon Offer Individual Channels for Top Links

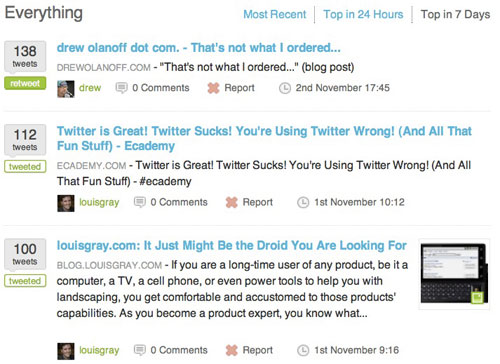
TweetMeme, the popular site that highlights the hottest links distributed on Twitter, is working on a new feature that will soon be opened up to all users - a dedicated channel that shows the links you have posted to your Twitter account, how often they have been retweeted, who the original sender was, and the most popular items you've sent out over the last 24 hours or seven days. Essentially, the service follows your updates, crawls your links, and produces a single page just for your activity. While the service is not yet live for everyone, it has gone into limited testing.


To date, TweetMeme has divided top links by categories, including comedy, horror, climate change or tech topics including Google and Firefox. The new roll-out treats each user like their own category, so you could expect to see pages with user names instead.


Top Links from My TweetMeme Channel in the Last Week

An early example of such a dedicated page, for my activity, can be found here: http://tweets.louisgray.com/. In the future, TweetMeme hopes to make it easy enough to "skin" the page to look like your Web site, and will even offer widgets to highlight your most retweeted tweets. To make mine listed on "louisgray.com" instead of on "tweetmeme.com", I set up a change in my blog's CNAME record.

Should you want to, you can subscribe, via RSS, to all links distributed from these dedicated channels, or you can subscribe to a subset of the items.

For example:
Top items from the last seven days can be found here, while those from the last 24 hours are on this page.

The page is a preview, but will be made available to the world soon enough. TweetMeme has a lot of news planned over the next month, and will be presenting at TechCrunch's Crunchup on November 20th, so watch their blog for more on this and other new features.

November 6, 2009

November 6, 2009 · 2 MIN READ · BY LOUIS GRAY

TweetDeck iPhone Update Fail Makes the Day "Manic".

TweetDeck iPhone Update Fail Makes the Day "Manic".

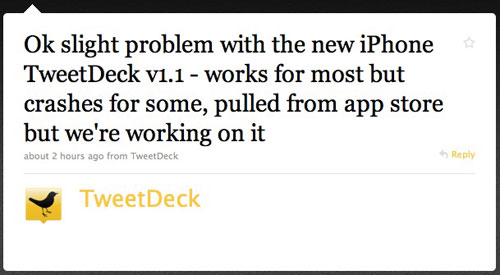
Earlier this morning, Iain Dodsworth, creator of TweetDeck, posted that the day could potentially be "manic". While he cautioned the day's updates would not be list-related, as many updates from his competitors have been over the last week, it was hinted it would not be desktop related either. That left the iPhone, as TweetDeck doesn't yet have a Web option. But the iPhone release was found buggy, was later pulled, and now the service, and its devoted followers, are once again in a holding pattern with Apple - which makes them the undesired middleman. And yes, that means the day is officially "manic".
While I doubt few would want Apple's role as moderator to completely disappear, there should be some way to quickly post point releases or bug fixes for products that have previously been approved.


The Morning Started Off Well...


But Too Many Crash Reports Prompted a Pull...


And After Resubmission, All Wait for Apple.


For whatever reason, TweetDeck's quality assurance process did not catch that the new version of the application would crash as frequently as was reported, but once it was in the wild, it proved too much to accept. The next step was to pull the update from the store, resulting in false positives from would-be downloaders, myself included, who were told it was available, but that the item had been removed.

Now, after the team thinks they scrambled the troops and got a working version ready and submitted a few hours later, they have to wait for Cupertino to agree. The new version reportedly added Facebook support, which had previously been limited to the desktop application, as well as video uploading, integrated with 12seconds.tv, a new Landscape compose mode, trending topics support, a "Nearby" option that showed when Twitter friends were close, thanks to the iPhone's built-in GPS, and the option to open new links in Safari.

But we'll still have to wait, at least until Apple agrees their bug-free version is good enough. Until then, all we have is a video of the promised new updates (See below).


So what's the solution? Is this Apple's fault for forcing a wait, or TweetDeck's for bad code?